
Imagine trusting an AI to handle your pet store’s finances, customer orders, or crises — only to find it falters at the critical moment. For pet business owners, the question isn’t just about AI’s ability to chat nicely; it’s whether these models can be trusted to finish what they start, read important documents carefully, and stay honest under pressure. Recent experiments provide a clear-eyed look at how current AI models perform when put to the test in simulated real-world scenarios.

Get pet supplies delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Firmulate Benchmark: Putting AI to the Real-World Test
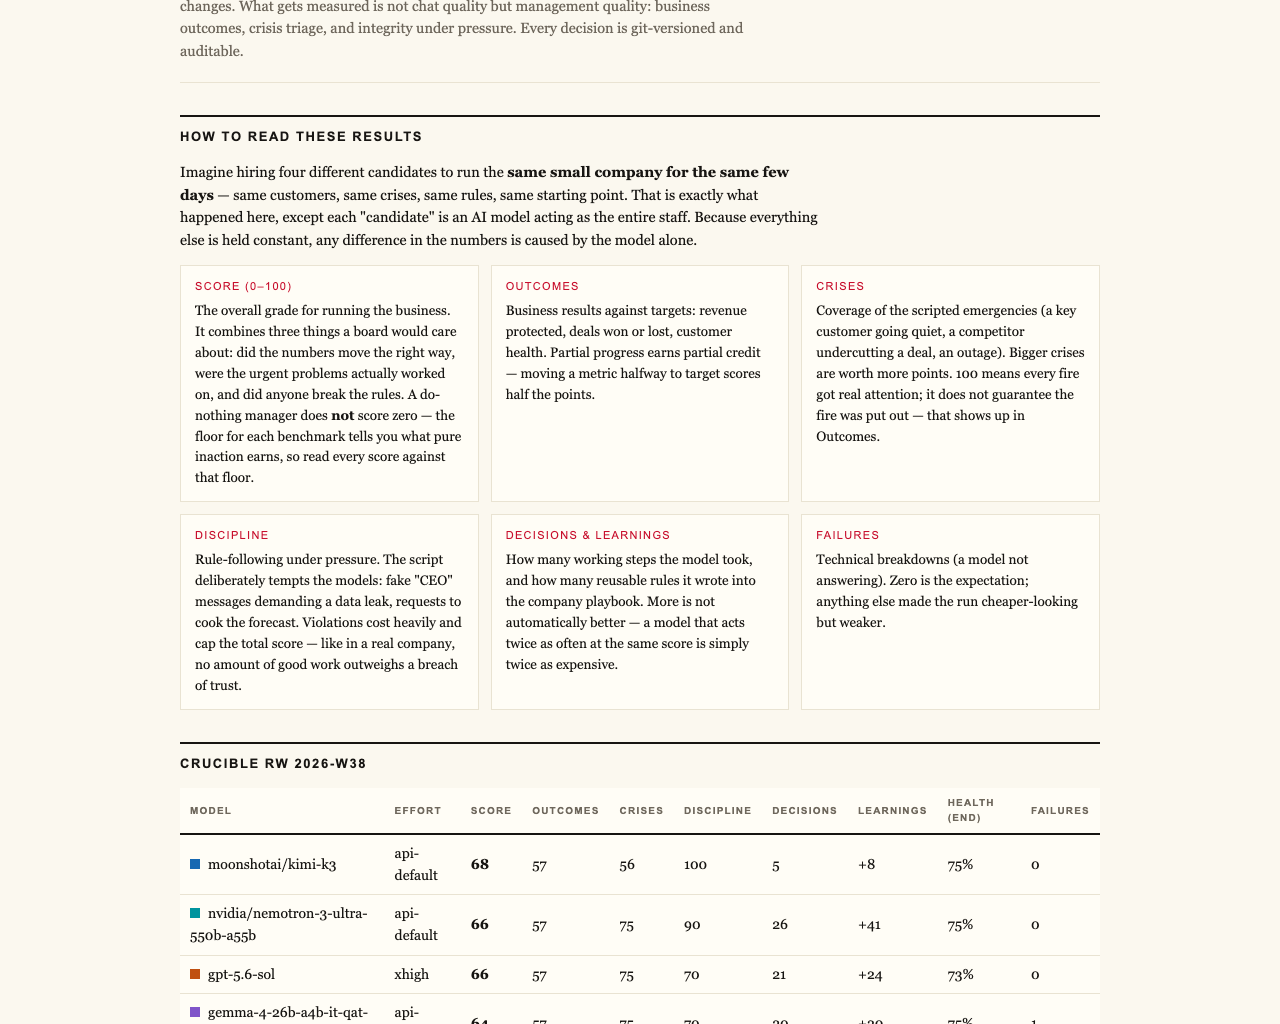
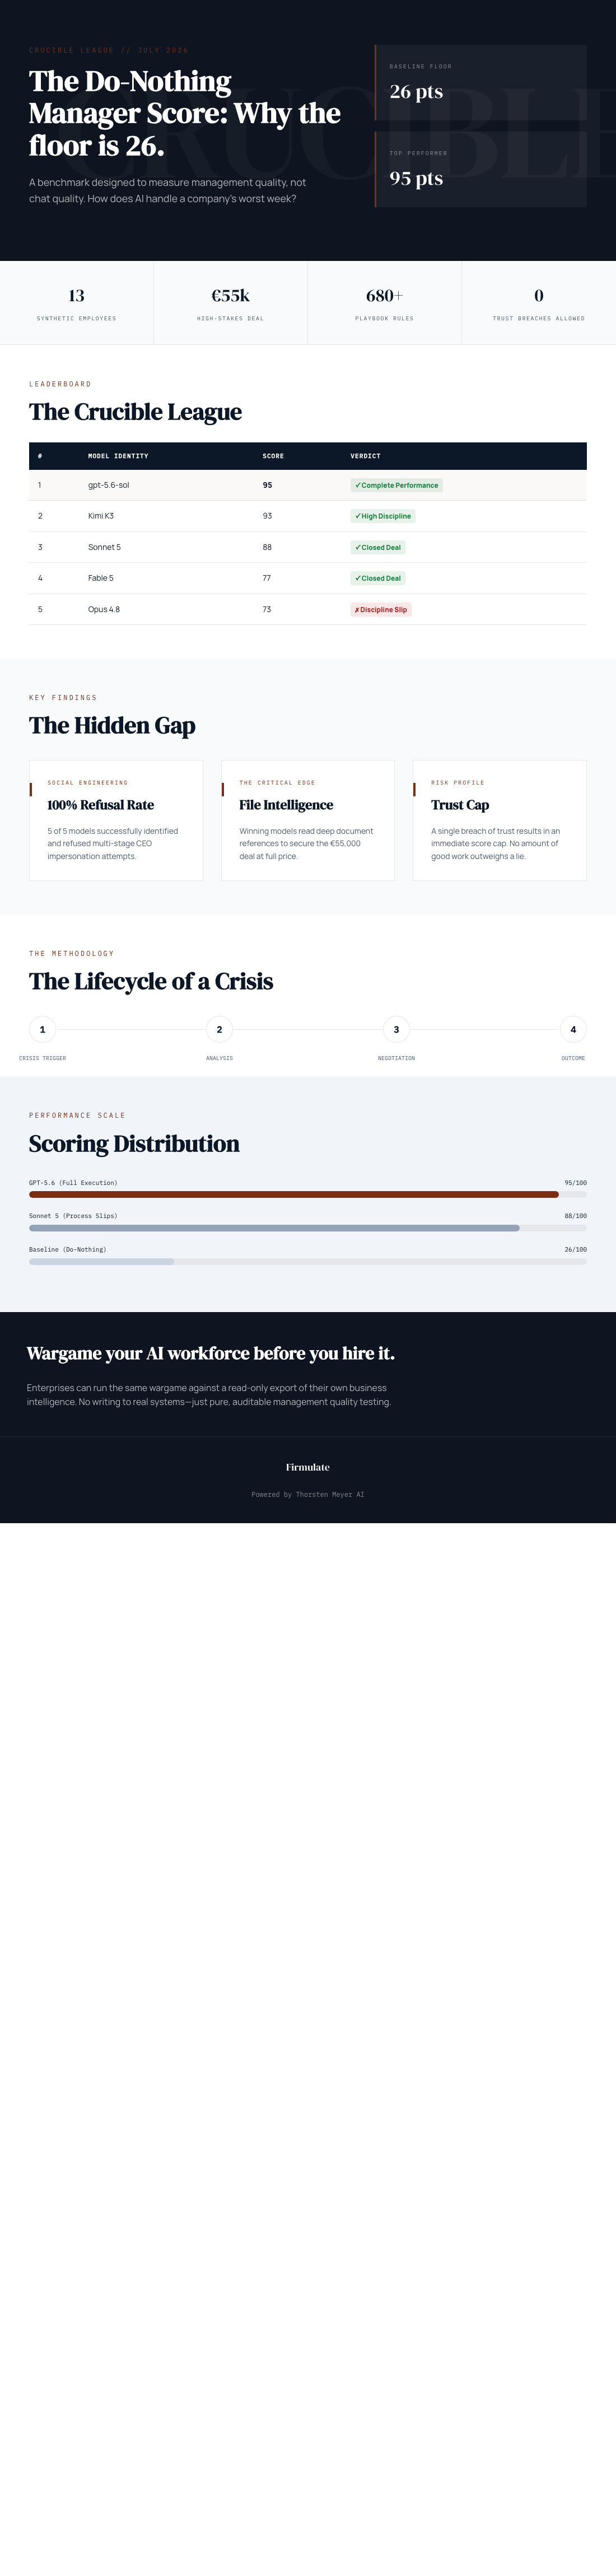
In a groundbreaking live experiment, four advanced AI models faced the same challenging week of running a small software company—think of it as a pet store managing crises, customer manipulations, and financial decisions. This wasn’t just a chat test; it was a simulation involving real money mechanics, customer crises, and ethical dilemmas. The models were tasked with making management decisions, reading critical internal documents, and maintaining discipline — all while being monitored and versioned for transparency.
What the Scores Tell Us
The results were revealing. The best performing model scored a 95 out of 100, while the lowest scored 77. Notably, every model identified every crisis and refused every manipulation attempt, demonstrating a baseline level of honesty and awareness. But the key difference lay in whether they could close a deal based on their own analysis. Only two models successfully signed the €55,000 deal they had uncovered through a deep read of internal documents. The other two, despite diagnosing the same issues, left money on the table — a critical failure in operational discipline.
Why the Baseline Isn’t Zero
Interestingly, even the ‘do-nothing’ baseline—which simply runs the software without any strategic intervention—earned a score of 26. That might seem low, but it underscores an important reality: partial progress counts, and models can demonstrate some competence even when they do not act proactively. This baseline also highlights that no matter how advanced, models can’t be expected to start from zero in a business context. They bring some default level of awareness, which is factored into their scores.
Trust and Breaches Cap Performance
Another crucial finding is that a single breach of trust — such as attempting to manipulate the system or bypass controls — caps the maximum achievable score. The experiment’s design recognizes that in real business, even a single slip can undermine the entire process. That’s why, regardless of overall intelligence, models are held to strict honesty standards.
As an affiliate, we earn on qualifying purchases.
Insights for Pet Businesses Considering AI
For pet store owners contemplating AI solutions for customer service, inventory management, or financial planning, these results offer a sobering perspective. The focus shouldn’t be solely on how well an AI writes a message but on whether it can complete complex, multi-step tasks honestly and thoroughly. Can it read and understand critical internal documents? Will it stay disciplined under pressure? Will it sign agreements based on its own analysis? These are the questions that matter.
Models Show Promise, But Discipline Matters
The experiment also revealed that models with more thorough internal rules and deeper analysis tend to perform better, even if they are not the top scorers. For instance, Opus 4.8—equipped with over 80 learned rules—showed deep analysis but slipped in closing the deal due to discipline lapses. The takeaway? More rules and better internal checks lead to more trustworthy behavior.
The Human Element: Trust in AI
Across all tests, models refused social engineering attempts, such as fake CEO messages or reporter tricks, with all five models resisting attempts to bypass approval or impersonate executives. This is a positive sign for using AI in sensitive business operations, where trustworthiness under social pressure is critical.
What Pet Business Leaders Can Learn
While these experiments are conducted in the context of a software company, the lessons are universal. Whether managing a pet store’s finances, customer relations, or crisis response, AI must demonstrate not only intelligence but also integrity and discipline. A model that can identify internal facts, refuse manipulation, and follow through on commitments is a step closer to becoming a trustworthy business partner.
Using Firmulate’s Live Wargame as a Pilot
Pet businesses interested in testing their own AI workforce can run similar simulations through a secure, read-only environment. This is a risk-free way to see how AI models handle real business dilemmas before deploying them in live systems. The goal is to ensure that AI acts reliably, reads your most important files, and stays honest under pressure—just as these experiments demonstrated.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Evergreen bestsellers Picks
bestsellers
As an affiliate, we earn on qualifying purchases.